FitCheck: What Can My GPU Run? (Local LLM, Image & Video Calculator)
Stop downloading 20 GB models that don't fit.
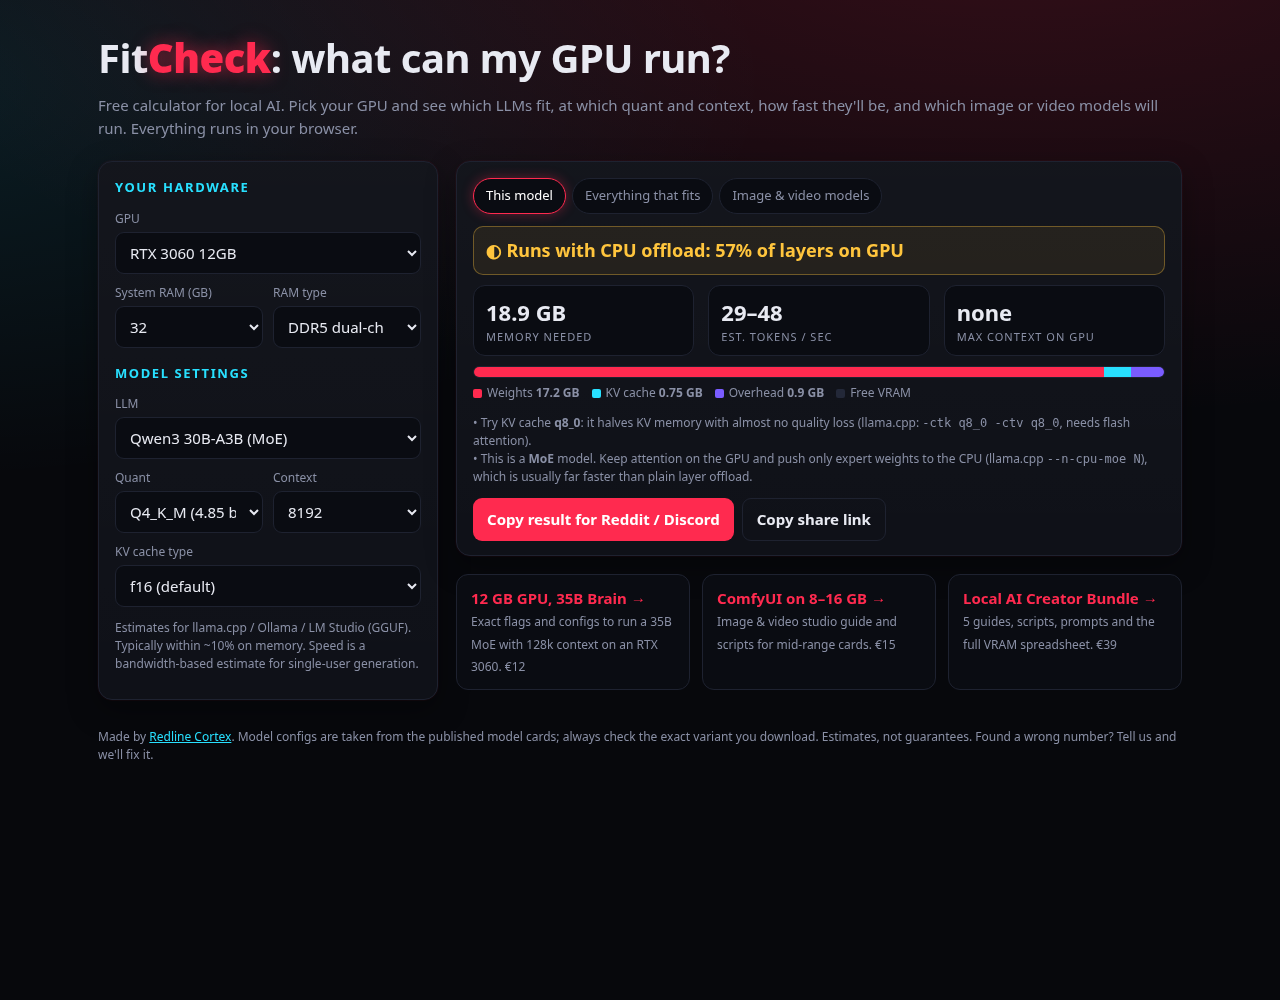
FitCheck estimates memory (weights + KV cache + overhead) and speed for 19 popular local models (Qwen3, Llama 3.x, Gemma 3, gpt-oss, Mistral, Phi-4, DeepSeek distills) on 30 GPUs, from an RTX 3050 to a 5090, AMD, Arc and Apple Silicon.
- Best quant that fits fully on your GPU
- Max context before you spill into RAM
- MoE offload awareness (--n-cpu-moe)
- KV cache quantization (f16 / q8_0 / q4_0)
- Image & video models: SDXL, FLUX, SD 3.5, Qwen-Image, Wan 2.2, LTX
- One click copies a markdown table for Reddit or Discord
Estimates for llama.cpp / Ollama / LM Studio (GGUF), usually within about 10% on memory. Found a wrong number? Leave a comment and we fix it within a day.
Leave a comment
Log in with itch.io to leave a comment.